YOLO Edge Optimization
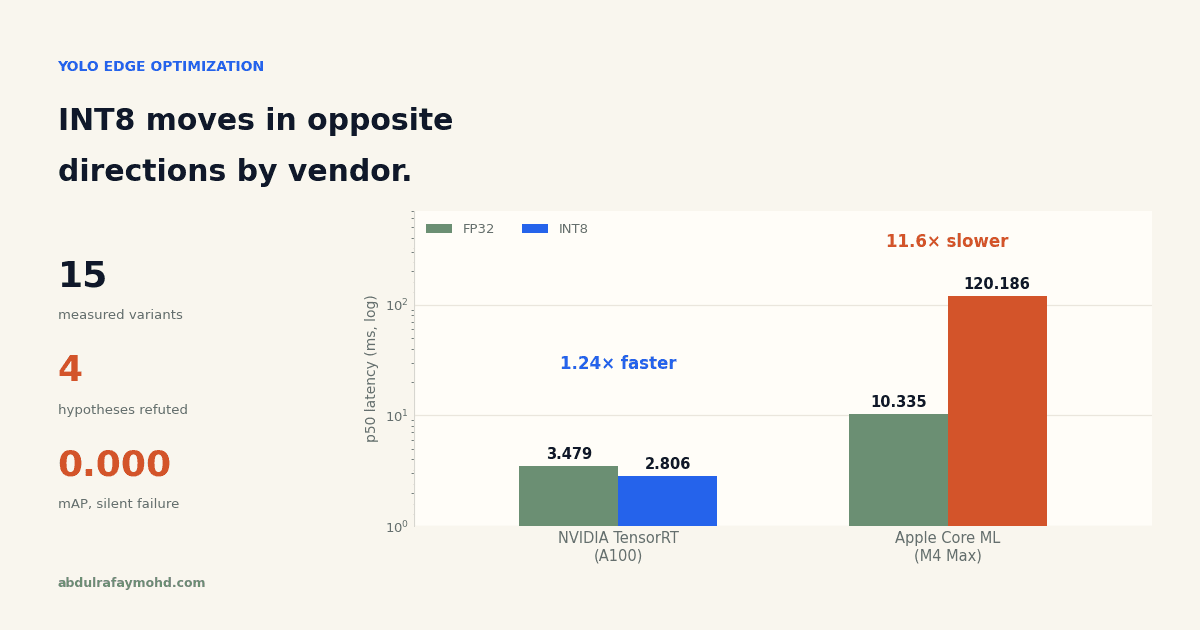
Took a YOLO detection model from research checkpoint to deployment across three accelerators and four runtimes, measuring what every optimization actually costs in latency, accuracy, and size. Found that export is 3.50× faster on NVIDIA TensorRT and 1.69× slower on Apple Core ML for the identical graph, and traced the regression to ten tensor-indexing operators in the NMS-free detection head that split the Core ML graph into eight partitions instead of five. Naive INT8 quantization collapsed the head to 0.000 mAP across all 5,000 COCO validation images without raising a single error; excluding 95 head nodes recovered it, and TensorRT quantized the same head successfully, establishing the failure as a quantizer limitation rather than an architectural one. Six findings documented alongside five hypotheses that failed under testing.